Anura PR Team
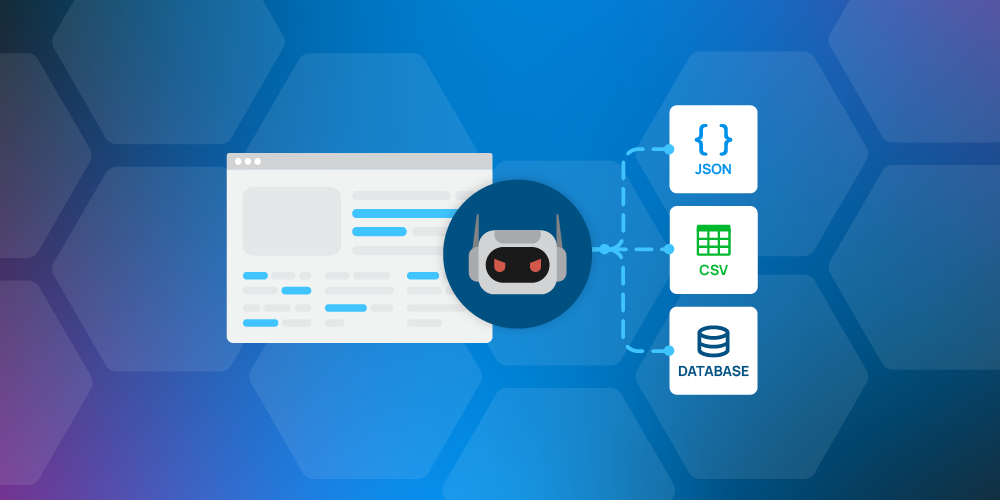
Web scraping is the automated extraction of data from websites. Instead of a person opening a page, reading it, and copying what they need, a program requests the page, pulls out specific information, and stores it in a structured format like a spreadsheet or database. Work that would take a person weeks can be finished in minutes.
A typical scraper works in three steps:
- Request. The bot sends a request to a web page, much like a browser does.
- Parse. It reads the page's underlying code and picks out elements such as prices, product names, descriptions, images, reviews, or contact details.
- Store and repeat. It saves the data and moves to the next page, often thousands or millions of times, on a schedule.
Web Scrapers range from simple scripts written in an afternoon to sophisticated systems that rotate through thousands of IP addresses, imitate human browsing, and adapt when a site changes its layout.
How Scraping Is Used Maliciously
Competitive Price and Inventory Theft
Competitors deploy web scrapers to monitor your prices, stock levels, promotions, and product catalogs, often in real time. They can use that intelligence to undercut you by a few cents on every item, time their sales against yours, or learn which products are selling best. Some operations go further. Job postings for scraping developers openly describe the goal: find products on other sites that can be resold on marketplaces for a guaranteed margin. Price scraping is surprisingly easy to do.
Content and Intellectual Property Theft
If your business depends on original content, such as product descriptions, reviews, listings, articles, research, or gated resources, web scrapers can copy it. The stolen material is republished on competing sites, sold to third parties, or used to build copycat storefronts. Duplicate versions of your content can also dilute your search rankings, since search engines may struggle to tell which version is the original.
Harvesting Personal and Sensitive Data
Data Scrapers can target restricted areas, user profiles, directories, and anything else that exposes personally identifiable information. Harvested contact details and account data can be sold on the dark web, used for phishing and spam, or fed into account takeover and credential-stuffing attacks. Because the collection is automated and quiet, a business may not realize the data is gone until it shows up somewhere it shouldn't.
Fake Sites, Scams, and Lead Fraud
Scraped content is raw material for fraud. Criminals copy the text, design, and product photos of legitimate businesses to build convincing fake storefronts and phishing pages. They collect business details to fuel scam outreach, and they gather form structures and page data that help bots submit fraudulent leads and applications. For advertisers and lead generators, the same infrastructure that scrapes data can also click ads, submit forms, and fill a funnel with junk.
Scalping and Inventory Hoarding
Some bots scrape product pages to detect the moment a limited item becomes available, like concert tickets or a sneaker release, then buy it up before real customers can. The scalper profits, and your loyal customers blame your brand.
Unauthorized AI Training
Large-scale collection of website content to train AI models is a growing concern. Many site owners want a say in who collects their content and on what terms. Many of these crawlers ignore the rules site owners publish in robots.txt files, and some disguise themselves as well-known bots, so that control quietly disappears.
Why the Goal Is Removal
Some businesses respond to scraping by tolerating a certain amount of it, treating it as background noise. That approach makes little sense once you look at what scrapers deliver. The common, well-established crawlers, such as the major search engines, provide a service: they help people find you. Nearly every other scraping bot provides nothing. It doesn't buy, it doesn't subscribe, and it doesn't refer customers. Instead they take data and content, consume bandwidth, and leave behind a visit that looks like activity which can skew your data and decision making.
That's why the target should be removal of all non-common scraping bots from your website.
Why This Matters for Traffic Analysis
This is where scraping moves from a security problem to a business intelligence problem. Nearly every team in your company makes decisions using website and campaign data. If scrapers are counted in that data, those decisions rest on numbers that don't describe real people. Reports still generate and dashboards still look polished. The errors surface later, as missed targets, wasted budgets, and decisions that can't be explained. The cleaner the data going in, the more reliable everything downstream becomes.
- Inflated traffic and engagement figures. Every scraper visit adds to your sessions, pageviews, and unique visitors. Traffic appears to grow while the number of actual customers stays flat.
- Distorted conversion rates. Bots visit pages but almost never buy. When a large share of visits comes from scrapers, your conversion rate falls, and you may conclude your site, offer, or campaign is underperforming when it isn't and teams then spend time and money fixing problems that don't exist.
- Skewed behavioral data. Bounce rate, time on page, scroll depth, and click paths all assume a human is behind each session. Scrapers move through pages in ways no customer would, dragging averages toward meaningless middle points and hiding what real visitors actually do.
- Unreliable A/B tests. If bots are split across test variants, your results reflect automated behavior mixed with human behavior. A winning variation may be a fluke, and a losing one may be unfairly penalized.
- Wasted advertising spend and polluted audiences. When scrapers land on your pages, they can be added to retargeting pools and lookalike audiences, so you pay to advertise to software. Attribution suffers too, since bot visits can be credited to channels and campaigns that didn't earn them.
- Bad inputs for forecasting and models. Demand planning, inventory forecasts, pricing models, and machine learning systems learn from your traffic and behavior data. If non-human activity is part of that history, every model built on it carries the error forward.
- Misallocated budgets. Perhaps the most expensive consequence: when the data is wrong, budgets move to channels that look strong because bots inflated them, and away from channels that are quietly delivering real customers.
Making Removal Part of Standard Practice
Because scrapers keep evolving, removing them works best as an ongoing practice rather than a one-time cleanup. A few principles help:
- Act before the data is collected. A web scraper stopped at the front-end never takes your content and never enters your analytics. Cleaning bot activity out of reports after the fact is slow, imperfect, and often impossible.
- Keep it continuous. Data Scraping tools, services, and tactics change constantly. A defense that works this quarter may be sidestepped by the next, so ongoing protection and monitoring matter more than a single fix.
- Measure the before and after. When webscraping is removed, traffic totals usually drop while conversion rates and engagement metrics become more accurate. That drop isn't lost business. It's the removal of visits that were never going to become customers.
- Treat clean data as an asset. The value of removing website scrapers extends beyond the security team. Marketing, product, finance, and leadership all benefit when the numbers reflect real customers.
Where Anura Fits In
Anura exists to help businesses trust their traffic. By keeping fake and unwanted visitors out of your campaigns, lead flow, and analytics, Anura helps ensure that the sessions you count, the clicks you pay for, and the leads you follow up on come from real people who might actually become customers.
The result is a business that can measure its performance accurately, spend its budget where it works, and make decisions with confidence, because the data behind them is clean.
The Bottom Line
Web scraping is a foundational technology of the internet, and its abuse is now one of the most common ways businesses lose money, content, and competitive edge online. Competitors steal pricing, criminals harvest data and build scams, and unauthorized crawlers take what you built without asking.
With scraping volume rising, a large share of your traffic may be doing nothing but taking from you while quietly distorting the numbers you rely on. Removing non-common scrapers protects your content and your revenue, and it protects the data behind every decision you make.
If you'd like to see how much of your traffic is real, Anura can help you find out. Start by signing up for a free traffic quality audit today.